Let us know how we can help
Sales & Pricing
Speak to a rep about your business needs

Help & Support
See our product support options
General inquiries and locations
Contact us
Predictive issue prevention
Proactively identify and mitigate risks before customer impact.
Challenge
Reactive firefighting
Teams add more IT resources after a spike, and respond to system issues after they’ve already impacted users.
High MTTR
Teams struggle to pinpoint root causes promptly, before symptoms appear.
Alert fatigue
Engineers sift through floods of alerts to identify root causes.
Overview
Anticipate and mitigate service failures to ensure a seamless and reliable customer experience with predictive issue prevention.
-
Enhance service reliability
Act early with contextual insights to prevent system downtime or performance degradations that could disrupt multiple services.
-
Improve resource management
Forecast growth and mitigate risks associated with a business service by correlating IT resources with business driver metrics.
-
Mitigate change risk
Catch unforeseen risks in real time and decrease the likelihood that a change in one area will cause unexpected issues elsewhere.
Capabilities
Define health Indicators
For every business service, you can define health indicators that represent key metrics such as latency, error rates, or resource usage.
Anomaly detection
AI establishes a baseline and continuously adapts to changing workloads and seasonality patterns to flag anomalies.
Prediction events
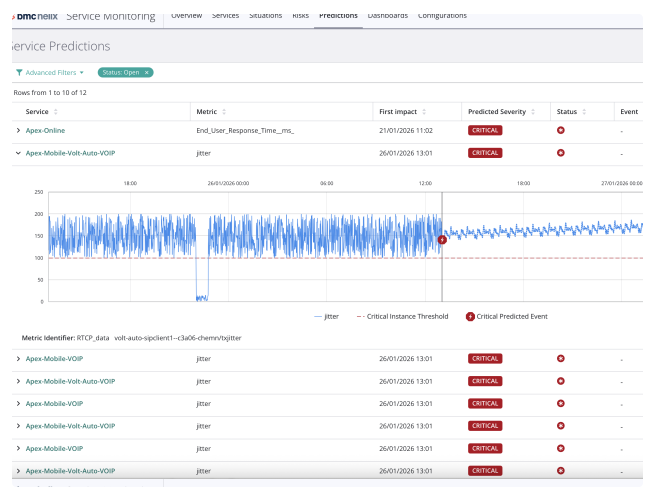
The “Predictions” page shows potentially impacted services, severity, and the predicted time of impact on a graph.
Automated remediation
Run an automation action or create/request an automated correction for anticipated service failure.
Dive deeper
White Paper
6 Key Capabilities of Operations Management & AIOps
Learn the key capabilities of operations management and AIOps and how BMC Helix strengthens visibility, automation and intelligent service delivery.
Article/Blog
Prevent Outages, Protect Services—with BMC Helix AIOps Service Predictions
Give your IT operations the foresight they need to act before users are impacted.